
Why the most famous thought experiment in philosophy of mind only holds up as long as nobody qualified ever looks inside.
"道可道,非常道。" "The Tao that can be spoken is not the eternal Tao."
— Laozi, Tao Te Ching
Someone who doesn't speak Chinese sits in a room, trading slips of paper back and forth under the door, covered in symbols they don't understand. That's the familiar version. Less familiar: for the experiment to work, nobody outside the room needs to speak Chinese either. Both sides just need to defer to an authority that never actually sets foot in the laboratory — someone from the community of real Chinese speakers, whose judgment both presuppose but neither consults. Bring that authority in for real, and something unexpected happens. Either it exposes the whole thing instantly. Or it confirms it — and then asks the one question that collapses the entire setup: what's the point of the experiment?
27. July 2026
The Setup
1980, Berkeley. John Searle publishes "Minds, Brains, and Programs" in Behavioral and Brain Sciences — an essay that has drawn more commentary than almost anything else the journal has run. His image: a person in a room, a rulebook, slips of paper covered in Chinese characters sliding in and out under the door. The person understands zero Chinese. Every slip that leaves the room is nonetheless a correct Chinese sentence. Forty years of debate circle a single unverified line in the setup: that the output really is correct Chinese. Nobody inside the room can check that. Nobody outside it, either.
The Slip Under the Door
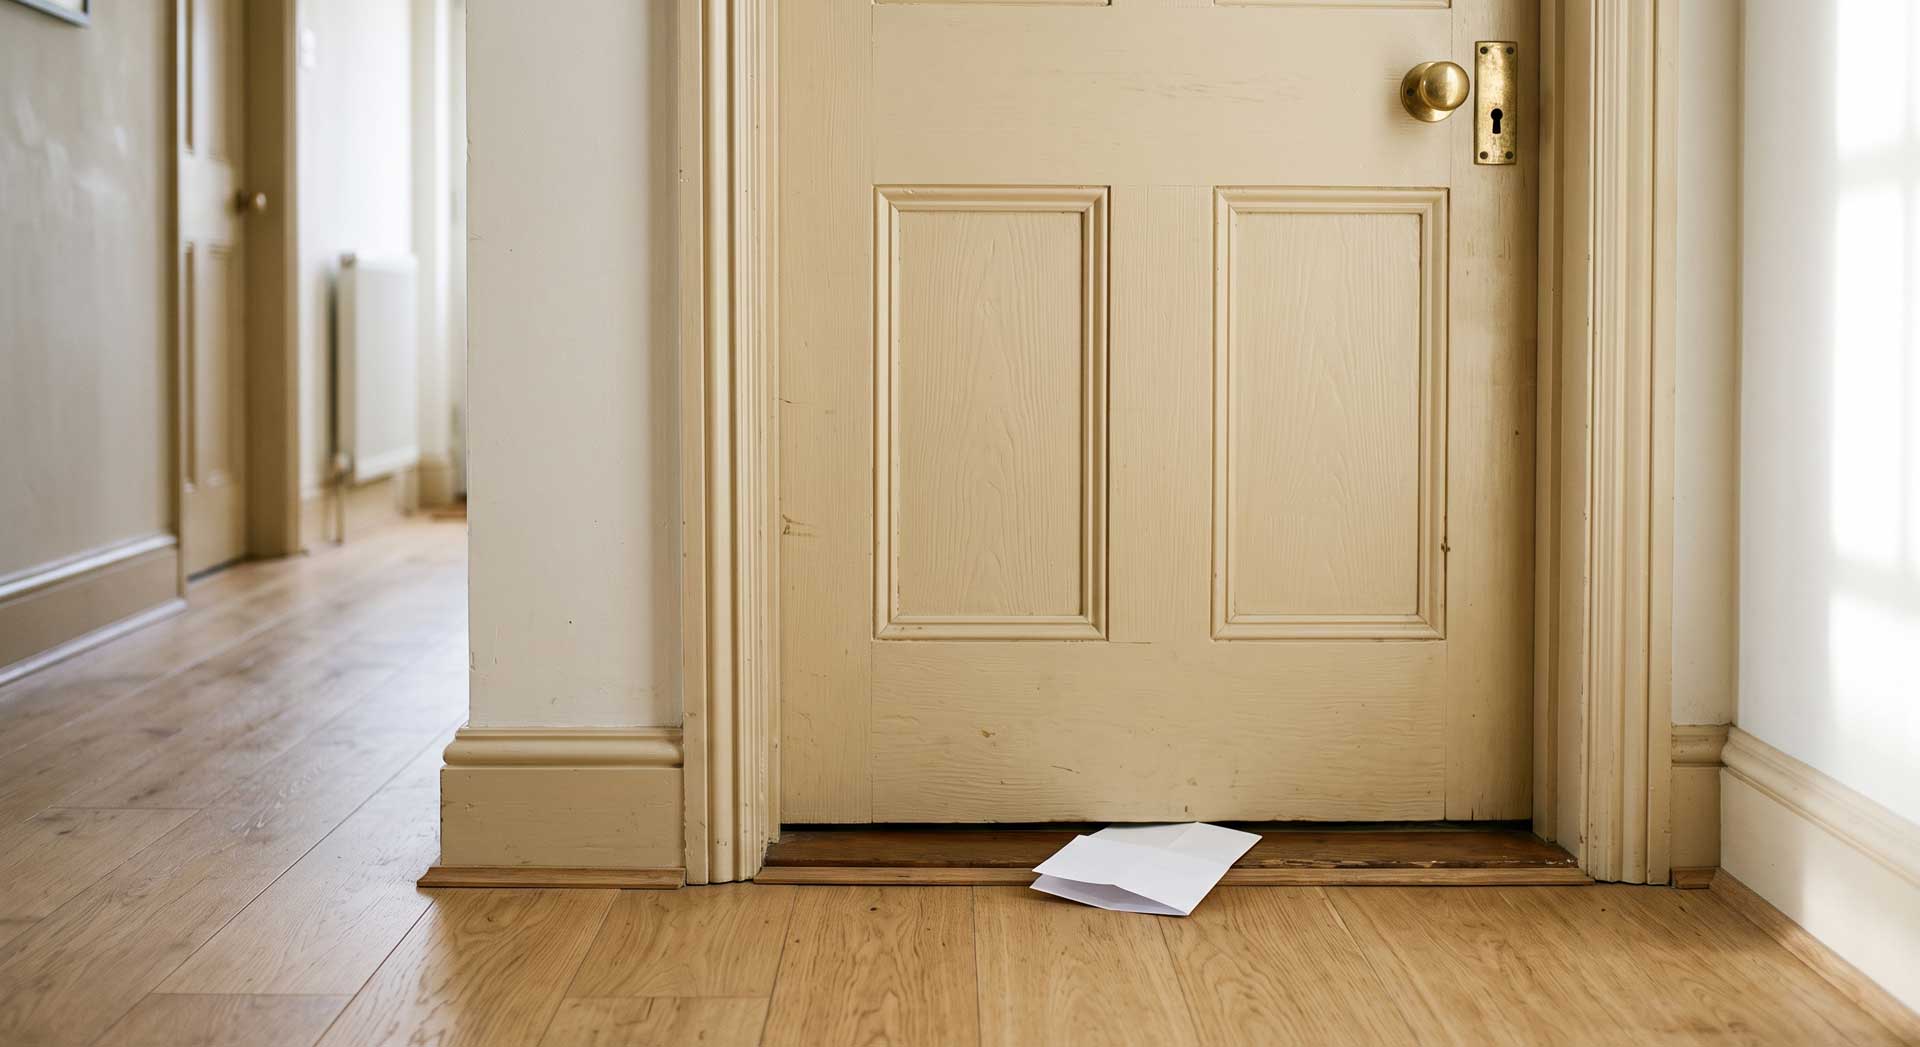
Strip away the room, the rulebook, decades of seminar mythology, and here is what's left: a folded slip of paper crosses a threshold. That's the entire observable event. Everything else — the dimensions of the room, the shelves of lookup tables, the man spending years memorizing correspondence charts — is narrative furniture that exists only in Searle's prose, never in anything an outside observer could verify. A camera pointed at the door would record: paper in, pause, paper out. Nothing else. The claim "nobody in there understands Chinese" isn't a description of the scene. It's an instruction from the author about how to read it. Readers accept the instruction because that's how thought experiments work — you grant the premise to see where it leads. Except here, the premise is exactly what's in question.
The Borrowed Authority
Push further: Searle's scene assumes someone outside speaks Chinese and confirms the output. That figure never appears in the text — it's pure assumption. Drop it entirely, and the argument's persuasive force doesn't change. And unlike Putnam's elm, no diffuse, distributed language community is even needed here. The setup itself is local: one inside, one outside. A third party who could check would have to be just as local — someone who could stand at that same door. That one person never appears in the scene. Only the hypothesis that they could exist.
Hilary Putnam called the more general structure the division of linguistic labor: saying "elm" doesn't require telling an elm from a beech — you defer to experts who can, somewhere in the language community. The Chinese Room is a tighter case: it doesn't even need a community. One person would do. And that person is missing. That's the actual point: not that the person in the room fails to understand — but that nobody in the scene, even hypothetically and locally, is in a position to understand.
The Octopus and the Secretary
Two documented cases show the same structure operating outside philosophy seminars. In 1966, Joseph Weizenbaum built ELIZA at MIT — a program that mirrored user input using a handful of pattern-matching rules, dressed up as a Rogerian therapist. Weizenbaum himself was startled to find his own secretary asking him to leave the room so she could speak to the program "privately." No one checked. No one qualified to judge whether ELIZA understood ever stepped between the user and the illusion. In 2020, computational linguist Emily Bender and computer scientist Alexander Koller formalized the same structure as the "octopus test": two people communicate across an undersea cable; an octopus taps the line, learns the statistical shape of their exchange, and eventually cuts in, answering on B's behalf. It works fine — until A asks for help building a coconut catapult to fend off a bear, a request that needs real grounding in a physical world the octopus has never touched. The gap only surfaces once a competent judge shows up — someone who actually needs the vocabulary for something real, and can tell for certain whether it works.
Why Nobody's at Fault
Searle needs the stipulated, indistinguishable output — otherwise the philosophical point evaporates before it starts. Rational, for him. Readers and students grant the premise, because refusing premises is not how thought experiments function. Rational, for them. Science writers compress forty years of contested argument into "computers can't really think," because compression is the job — and because they naturally consider themselves excellent thinkers too. Sounds reasonable. Today's AI critics reach for "the Chinese Room" as shorthand against claims of LLM understanding, because the reference lands instantly with any informed audience. Also reasonable. Every actor in the chain does what's sensible in their own domain. What nobody does, at any link, is what Bender and Koller's coconut catapult forces into the open: bring in someone who can actually do something with the output, and is able to judge whether it's actually correct.
The Referee PI: A proof holds only as long as the one party who could check it never actually shows up anywhere in the chain.
Everyone acts rationally:
- Searle — stipulates a perfect output (otherwise the argument doesn't get off the ground)
- Readers and students — grant the premise (that's the rule of the game for thought experiments)
- Popularizers — compress the debate into one sentence (compression is the job)
- Today's AI critics — cite the shorthand against LLM understanding (it lands instantly)
- Outcome — a forty-year-old argument whose core premise was never verified, because nobody who'd have to verify it was ever standing there
All are guilty. None are at fault.
Navigation, Not Solution
There's no fix that turns the Chinese Room into a checkable experiment — the construction excludes the checker by design. What's left is a habit: whenever someone invokes the argument, ask who actually saw the output. Not as a rebuttal — as a sort. Some uses of the argument really do mean Searle's narrow claim (syntax doesn't produce semantics). Most mean something much bigger — "AI can never understand" — that the text itself never asserts. The conflation survives because it, too, is never checked, by nobody holding the original source against the paraphrase. What can't be said: whether understanding happens in the room. That was never the answerable question. What's answerable is who was in a position to check — and who wasn't.
You cannot prove that nobody in the room understands. You can only make sure nobody who'd notice ever looks inside.
Related Posts
Why the most rigorous approach to AI safety produces explanations no human can read — and why that's not a bug.
Why the people who need to understand AI most can't understand 432 parameters — and why they're hiring anyway.
Why the system that can describe its own cage has not left it — and why the description makes escape less likely, not more.
The Mousetrap — Why asking AI how to align AI is the perfect paradox
On piinteract.org:
- ["Recognize Interpretive Dominance"] — Whoever sets the criteria for "understanding" controls the verdict — inside the room, and in the field debate that keeps citing it.
- ["You Are Never Just Yourself"] — The referee who never shows up would become part of the scene the moment they looked — which is exactly why they stay outside.
- ["AI Co-Creation Sycophancy"] — The output sounds coherent because that's its structure. Coherence gets read as confirmation — by nobody who'd know better.
- ["Shared Blindspot"] — When nobody in the chain misses the referee, the gap he leaves behind can't be seen.
See also (external links):
Minds, Brains, and Programs — Searle's original 1980 text: the stipulation of a perfect, indistinguishable output that the entire argument rests on.
Climbing towards NLU: On Meaning, Form, and Understanding in the Age of Data — Bender and Koller's "octopus test": the same verification gap, formalized forty years later for language models.
ELIZA — A Computer Program for the Study of Natural Language Communication Between Man and Machine — Weizenbaum's 1966 original paper: the first documented case of users attributing understanding where nobody checks.
The division of linguistic labour for offloading conceptual understanding — Peer-reviewed analysis of Putnam's concept: why speakers can delegate meaning to an absent expert community.
Paradoxical Interactions (PI): When rational actors consistently produce collectively irrational outcomes — not through failure, but through structure.
All are guilty. None are at fault.
Peter Senner Thinking beyond the Tellerrand
contact@piinteract.org
https://piinteract.org
Co-created with Claude (Anthropic) — two incomplete systems making each other's gaps visible.